
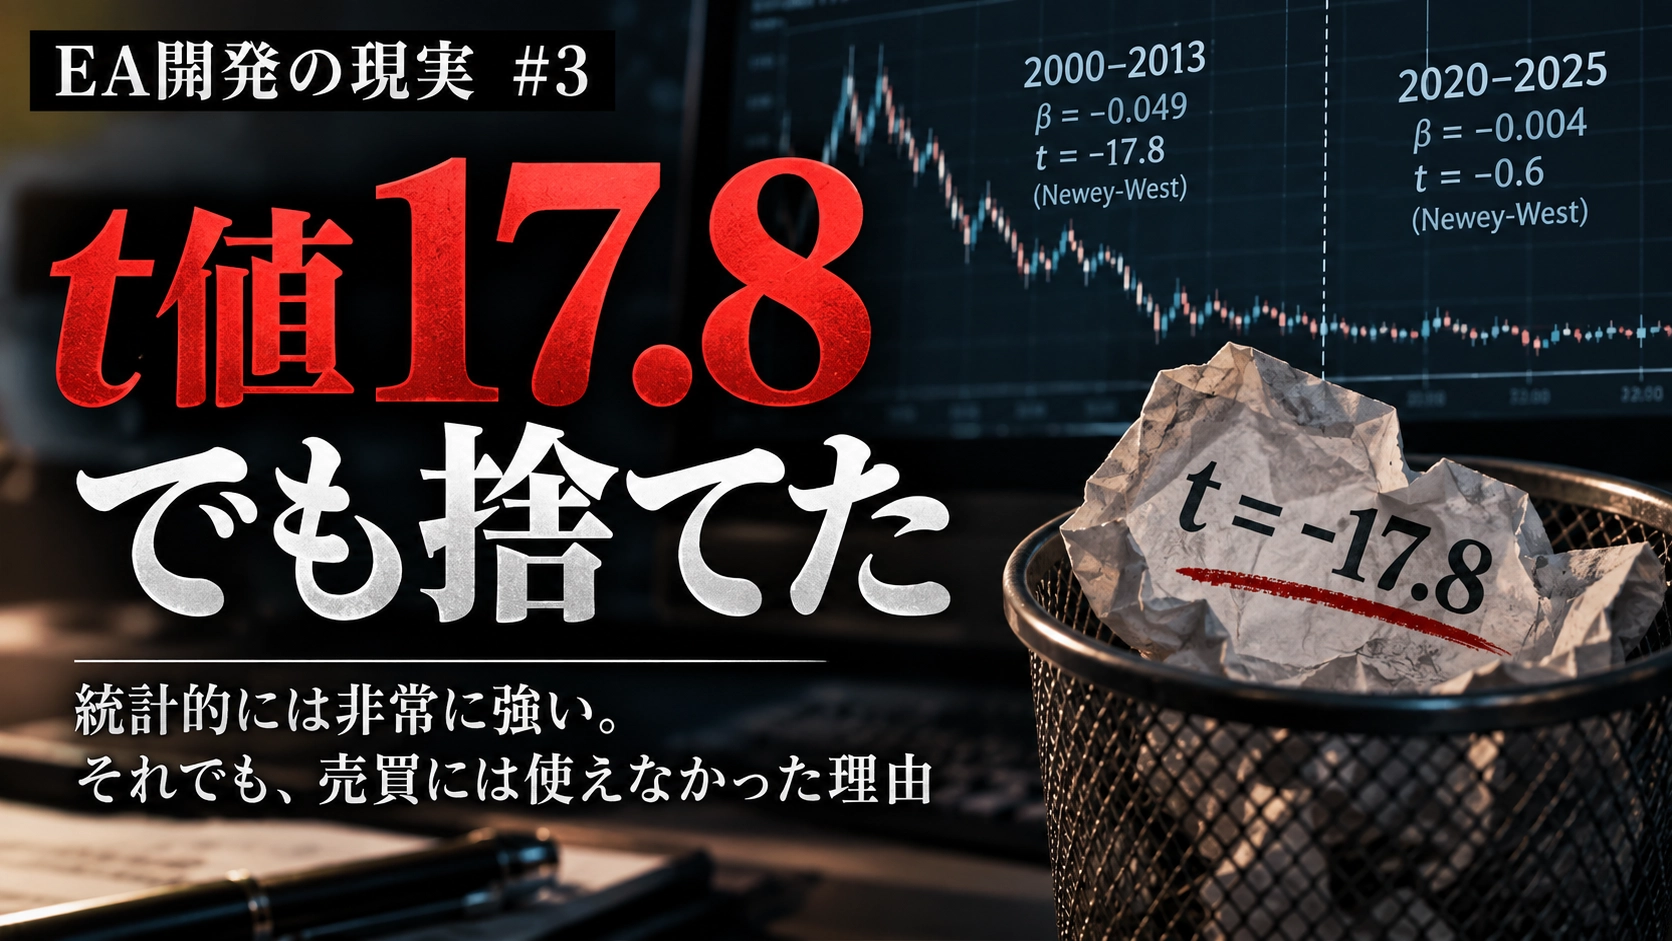
Even at a value of t 17.8, it was discarded
# I discarded even at t value 17.8. "Statistically effective" and "able to trade" were different things
In the first article, there is a case briefly mentioned.
In the old USDJPY, it was confirmed quite strongly, but recently it has almost disappeared, and it was not even large enough to exceed trading costs.
**I will write in detail about this case that I touched on a little in the first part.**
In the middle of the validation,
**t = −17.8**
appeared as a fairly large value.
Moreover, this is not a number calculated by simple standard error.
**It is calculated using Newey-West method that adjusts for autocorrelation in the data.**
Still, in the end I did not adopt this hypothesis as a trading strategy.
The reason is that,
**there is a difference between existing statistically and actually making money in practice.**
---
## Validating a hypothesis derived from a paper in real markets
What I tested was
a hypothesis of whether short-term price moves tend to reverse depending on the state of price fluctuations.
I moved ideas obtained from papers and research into the market data I use and tested them.
What I wanted to see here were
- whether the phenomenon exists in the first place
- whether it remains as time changes
- whether it is large enough to exceed actual trading costs
These three points.
I do not think that "because it is in a paper you will win."
I verify whether it can survive to practical use in the market.
---
## In the old USDJPY, it appeared quite strongly
Looking at USDJPY data,
from 2000 to 2013,
**β = −0.049**
**t = −17.8**
was the result.
(Source: design_A1_vol_regime_reversal_20260902.md:384)
This t-value is
**a value calculated using Newey-West (Bartlett, lag=10) method that adjusts for autocorrelation in the data.**
Because we overlapped using a 10-minute window, adjacent observations are not completely independent.
Even taking that into account,
historically quite strong results were confirmed.
In other words,
it is not a number like "the t-value became unusually large because adjacent data were treated as independent."
Until now, this has been favorable for the hypothesis.
---
## However, recently it has almost disappeared
When looking at the same phenomenon by era, the situation changes.
From 2020 to 2025,
**β = −0.004**
**t = −0.6**
had decreased.
(Source: design_A1_vol_regime_reversal_20260902.md:384)
The phenomenon that was strong before has almost become unnoticeable recently.
This is a very important issue for automated trading validations.
When summarizing across the entire period into a single number,
**the strong old era sometimes hides the recent weak era.**
Therefore I look not only at whether it was statistically significant over long periods, but also
**whether its effect remains up to recent times**
as well.
---
## "It was real in the past" does not justify trading now
The result this time does not mean that all past phenomena were fake.
Rather the opposite.
From 2000 to 2013,
there was a high likelihood that it existed in a fairly clear form.
But,
**what truly existed in the past and what can be traded now are different issues.**
In markets, participants, liquidity, trading costs, algorithms, market structures,
and many other aspects change over time.
Therefore, a phenomenon that was strong in the past does not necessarily continue with the same strength in the future.
---
## There was another problem. The effect itself was too small
However, the reason I closed this hypothesis as a trading strategy was not only that it weakened recently.
There was a more direct issue.
Even in the strongest historical period,
when converting the predicted reversal magnitude into actual price moves,
**about 0.15–0.3 pip**
was the result.
Meanwhile, the observed spread was
**about 0.2–1.0 pip**
.
(Source: design_A1_vol_regime_reversal_20260902.md:390)
This reveals a very harsh reality.
**The movable price action we can predict was already on par with or less than trading costs.**
That is to say.
---
## Even if statistically correct, trading eliminates it
This is where I wanted to emphasize the most this time.
If,
“the next price move reverses on average slightly”
the prediction is statistically real,
if the price range is smaller than trading costs, it cannot be used for trading.
In extreme terms,
**you can be right about the future a little, but you lose when you trade.**
What is needed in automated trading is not only that the prediction is correct.
What is required is
**the predictable price range must exceed the trading frictions by a sufficient margin**
.
If it does not reach that,
even if the statistical model is interesting,
it fails as a trading strategy.
---
## A large t-value does not mean large profits
When the t-value is large, you may think,
"It’s a very strong phenomenon, perhaps?"
However, the t-value itself does not represent the actual profit amount.
Roughly speaking,
**how large the estimated effect is relative to the estimation error**
is what the number shows.
With a large amount of data and a small phenomenon that repeats stably,
even a economically small effect can yield a large t-value.
That was exactly the case here.
Statistically very clear.
But the per-trade payout was small.
Therefore,
**we must separate "statistically strong" from "economically large."**
And realized that this distinction matters.
---
## Now I divide evaluations by stage
Since this experience, when I look at a strategy, I have started to consider at least the following distinctions.
- Is there predictive power?
- How does it fare with exit?
- Can it exceed the spread?
- Can it exceed holding costs?
- Does it also work with the product specifications of the actual broker I use?
Putting everything together,
"High PF (profit factor) = OK" is not enough to decide.
At each stage, some prospects may fail at the next step.
For this hypothesis,
**the phenomenon has been historically confirmed.**
But,
**it did not survive as a trading strategy.**
That was the case.
---
## A zero result can also be valuable
Backtesting often yields more impressive results like
“found something that wins.”
But in reality,
**it is also valuable to determine what cannot be used.**
This time too,
if I had stopped at just checking the t-value,
I might have retained a quite promising hypothesis.
But,
- divide by era
- look at the effect size
- compare with actual trading costs
And after going that far, I did not adopt it as a trading strategy.
---
## The conclusion of this time
The conclusion from this validation is
**that statistically existent edge and tradable edge are not the same**
.
In the old USDJPY period,
even after adjusting for autocorrelation,
**t = −17.8**
showed a very strong result.
Nevertheless,
the effect itself has mostly disappeared recently,
and even in the historically strongest period,
the amount that could be predicted did not exceed trading costs sufficiently.
So I did not deny the phenomenon itself, but I closed it as a trading strategy.
---
## In conclusion
In the first part, I wrote about
**"Creating a winning EA" and creating a trustworthy EA are different**
In the second part,
**the reason I discarded even a 99.5% win rate**
was discussed.
And this time,
**the reason I discarded even a t-value of 17.8**
is discussed.
What is common among the three is that you should not aim for a good number as the goal.
Whether it is win rate,
PF,
t-value,
you should think separately about what that number means and what it does not.
The more favorable the number, the more you should doubt it.
In automated trading validations, I think this level of caution is appropriate.
※This article does not recommend any specific EA, financial product, or individual trading decision. It records the validations performed and their methods.